> ## Documentation Index
> Fetch the complete documentation index at: https://docs.evermind.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# EverOS Cloud
> The persistent, self-evolving memory layer for every AI product you build.
EverOS Cloud is the memory engine for developers. Give every AI product you build
(an agent, an assistant, or any AI app) a persistent, self-evolving memory, so a
stateless LLM becomes something that remembers and grows, without you operating any
memory infrastructure.
Today's models are capable but forgetful: each session resets what they learned
about the user, the task, and the mistakes they already made. Stuffing the context
window is slow and expensive, and a bolted-on vector store only retrieves, it never
learns. EverOS turns conversations, tasks, and domain knowledge into persistent,
retrievable, evolving memory, so your product gets more useful the more it is used.
## What EverOS gives your product
Records each agent run as a **Case** and distills recurring Cases into reusable
**Skills**, so your agents get better at a task the more they run it.
Two tracks: **User Memory** (who the user is) and **Agent Memory** (what the agent
has learned). Scope by owner, type, and user / agent / app / project / session.
Native multimodal: text, images, audio, docs, PDF, HTML, spreadsheets, slides,
and email become structured, searchable memory.
Keyword, vector, hybrid, or agentic search, resolving coarse Episodes down to
atomic **Facts** for verifiable recall instead of fuzzy summaries.
Add, search, edit, and delete. Memory is a governable asset you control, not an
append-only black box.
See exactly what's stored (profiles, episodes, agent cases and skills) in the
console, browsable by owner, type, and time.
The same API on managed Cloud and self-hosted (Apache-2.0). Move between them for
compliance without rewriting code.
## How EverOS works (a quick glance)
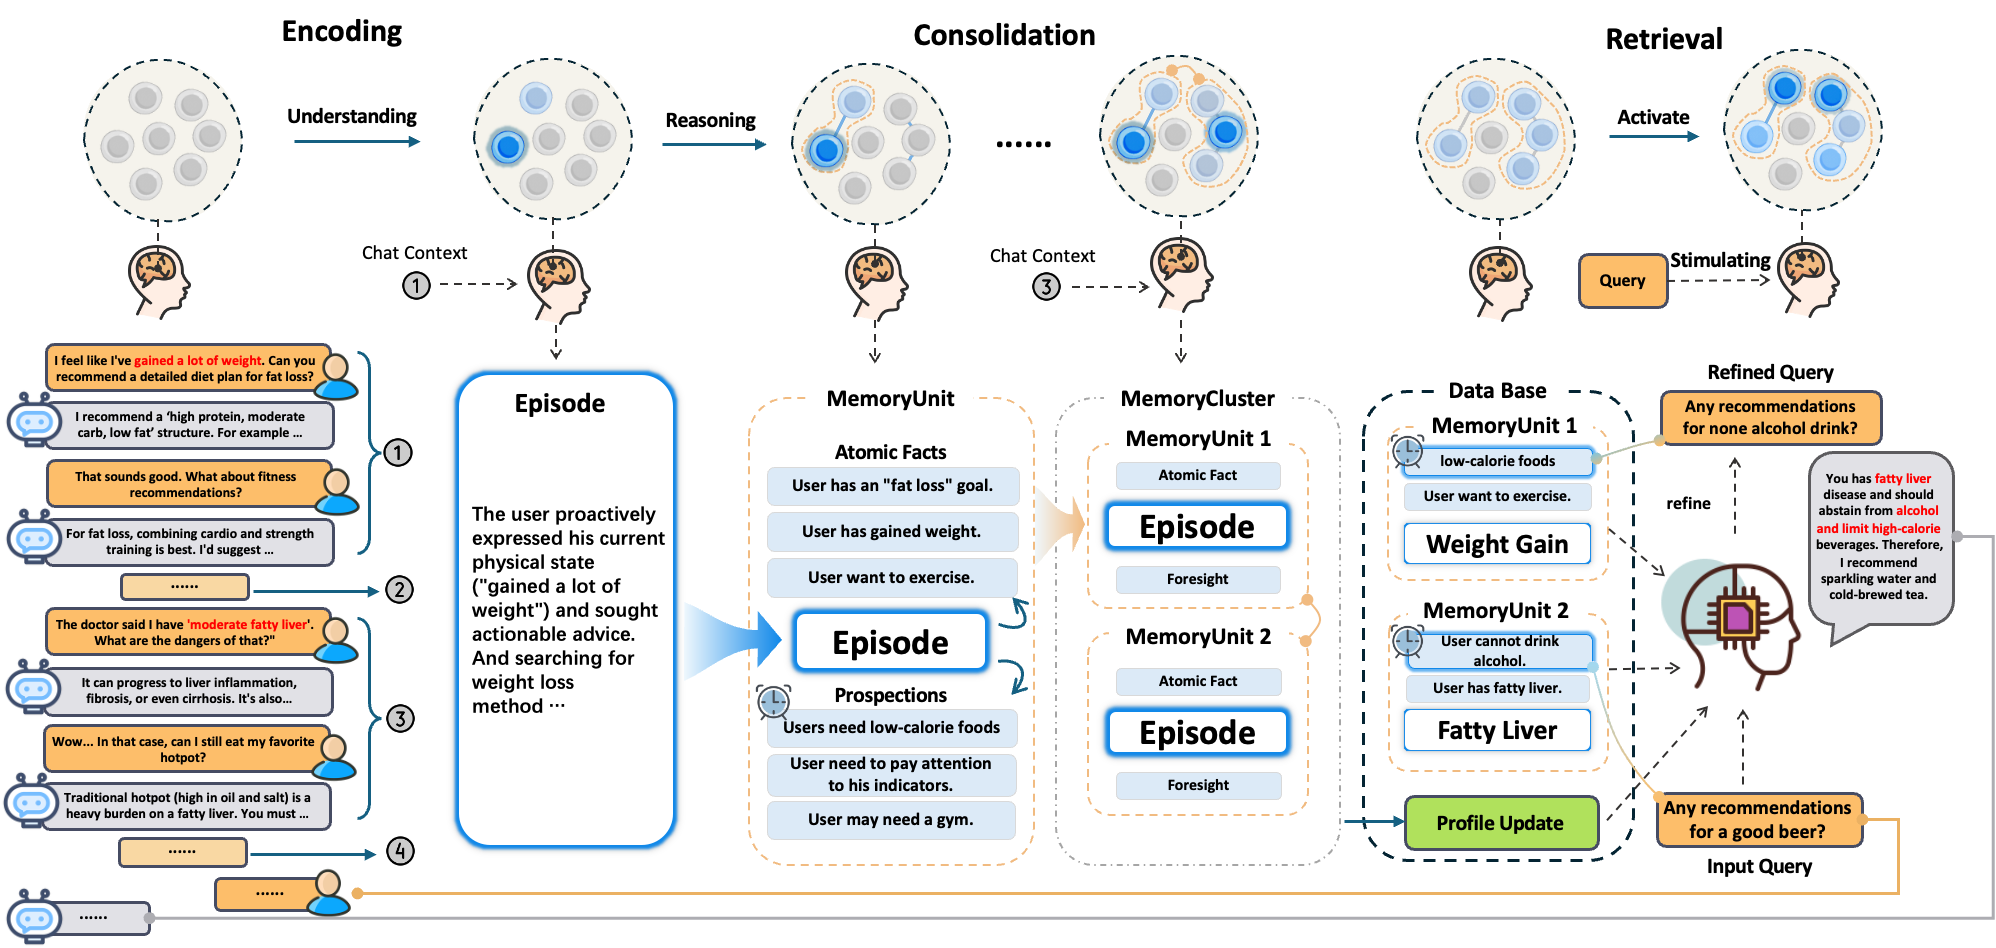 1. **Episodic Trace Formation**: EverOS monitors the continuous dialogue stream and uses semantic boundary detection to segment interactions into coherent events.
2. **Structured Encoding**: For each event, it synthesizes a **MemCell** containing a concise third-person **Episode**, atomic **Facts**, and time-bounded **Prospections**.
3. **Semantic Consolidation**: Instead of flat storage, MemCells are dynamically clustered into thematic **MemScenes** (e.g., "Health", "Work") to capture high-level contexts.
4. **Profile Evolution**: The system continuously distills these scenes to update a structured **User Profile**, separating stable traits from temporary states.
5. **Reconstructive Recollection**: Your agent retrieves context via hybrid search (BM25/vector/RRF) or **Agentic Retrieval**. EverOS navigates MemScenes, filters for time-valid evidence, and iterates until the retrieved context is "necessary and sufficient."
6. **Grounded Reasoning**: The agent uses the returned memories as grounded context to respond and plan, enabling long-horizon reasoning without replaying weeks or months of history in the prompt.
## Proven on public benchmarks
* **LoCoMo 93.05%** · **LongMemEval 83.00%** · **HaluMem recall 90.04%** — memory accuracy and anti-hallucination
* **+234.8%** peak task-success lift from the self-evolving skill engine
* **\~450ms** P95 latency · **>90%** fewer tokens than full-context (about 10× lower cost)
## Core memory operations
Extract memory from messages and interactions, across text and files.
Precise memory filtering based on owner, type, and metadata fields.
Context-aware retrieval (keyword, vector, hybrid, agentic) across every format.
## Continue to
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.